The Vanishing Horizon
By Lindsay Hiebert, Founder — August 2026
Why app developers can’t out-render the platforms — and what to build instead.
Last weekend I did something most founders avoid: I benchmarked my own product against the two biggest consumer AI apps on earth, with identical prompts and identical reference photos, and prepared to publish whatever happened.
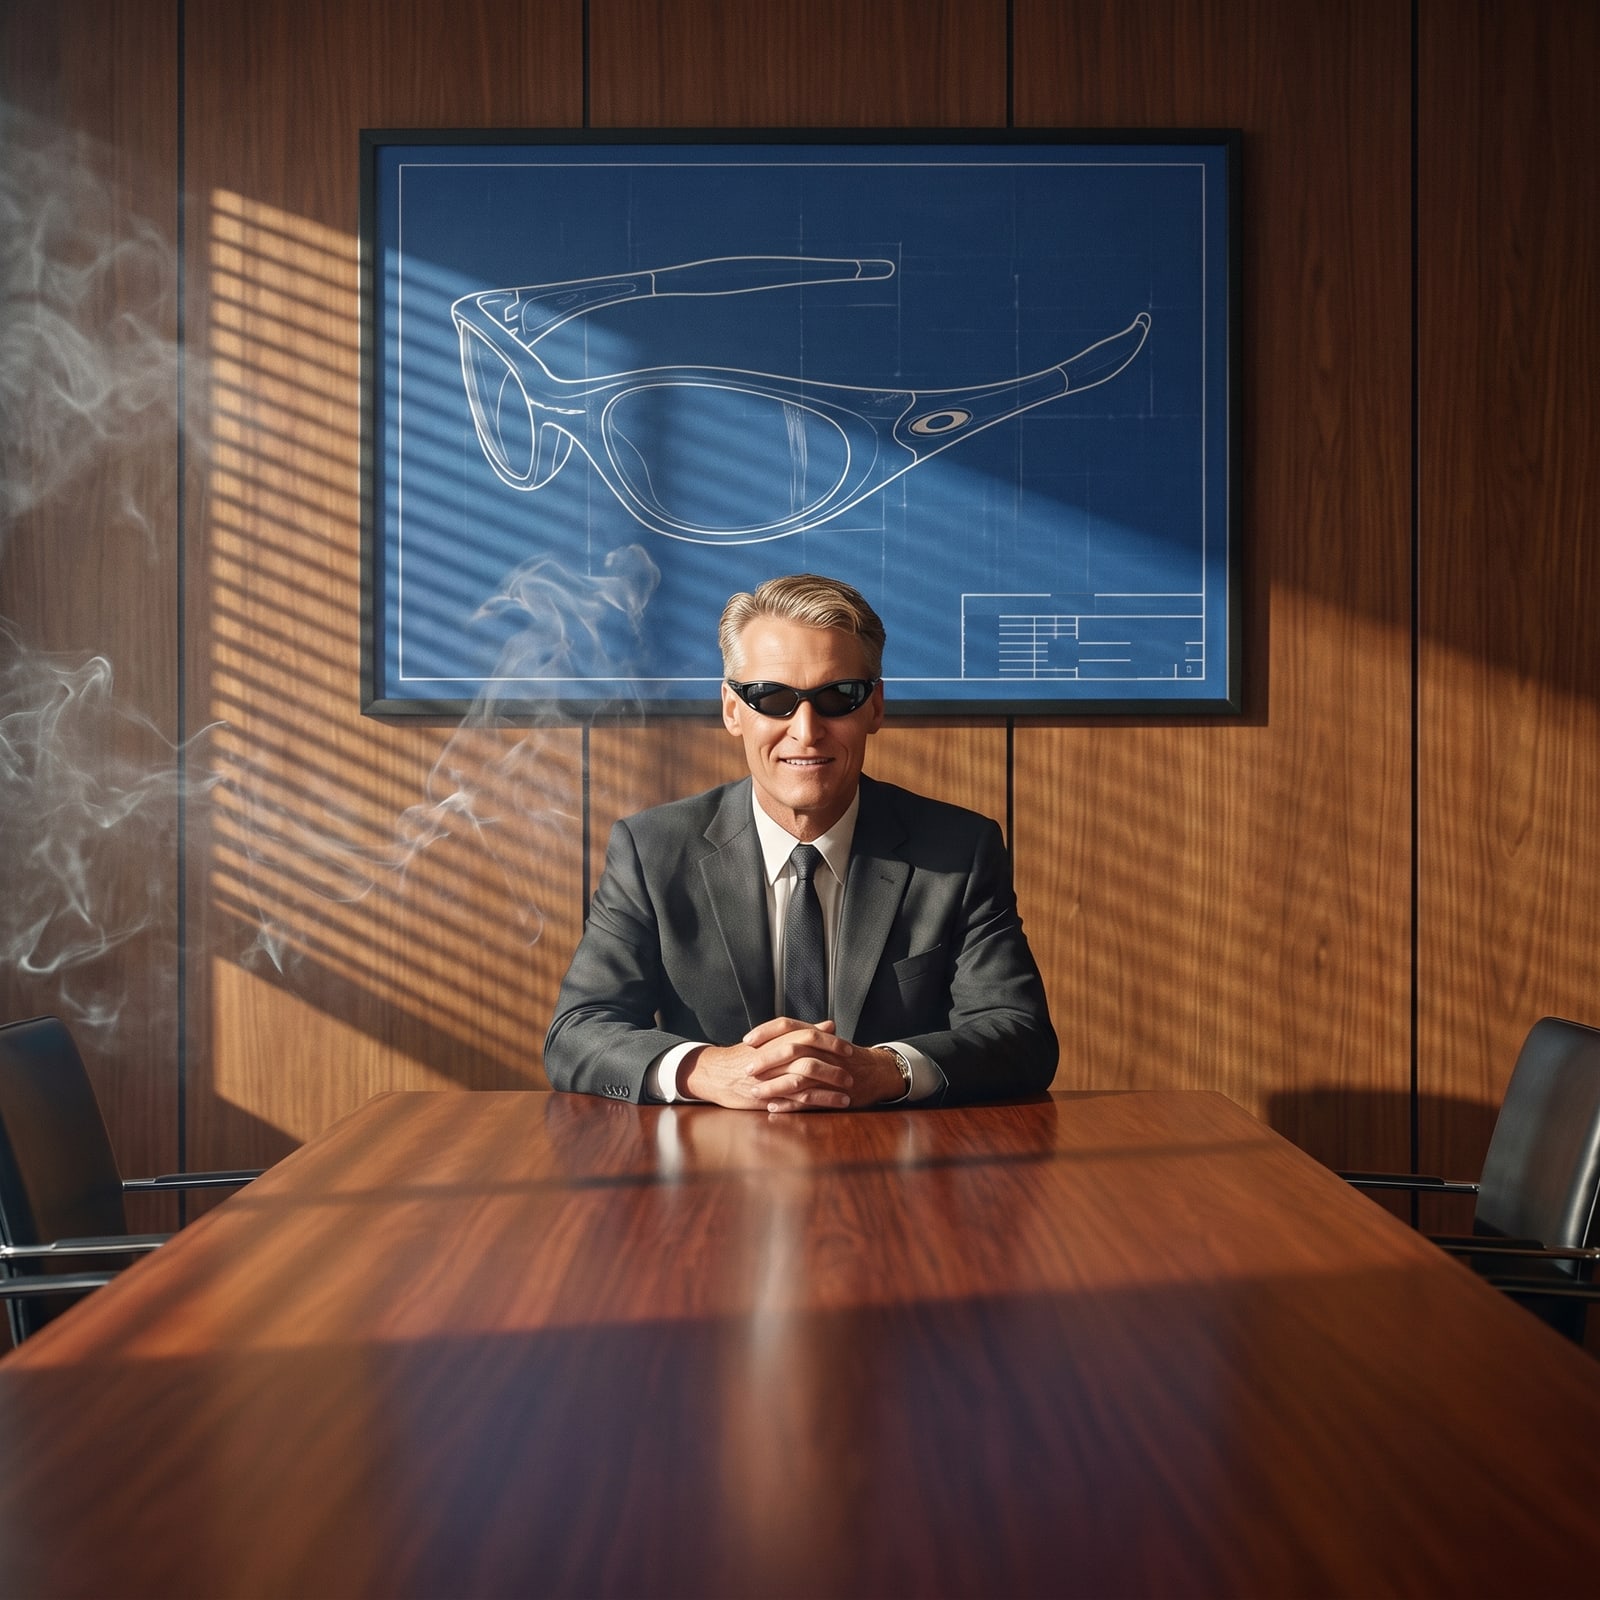
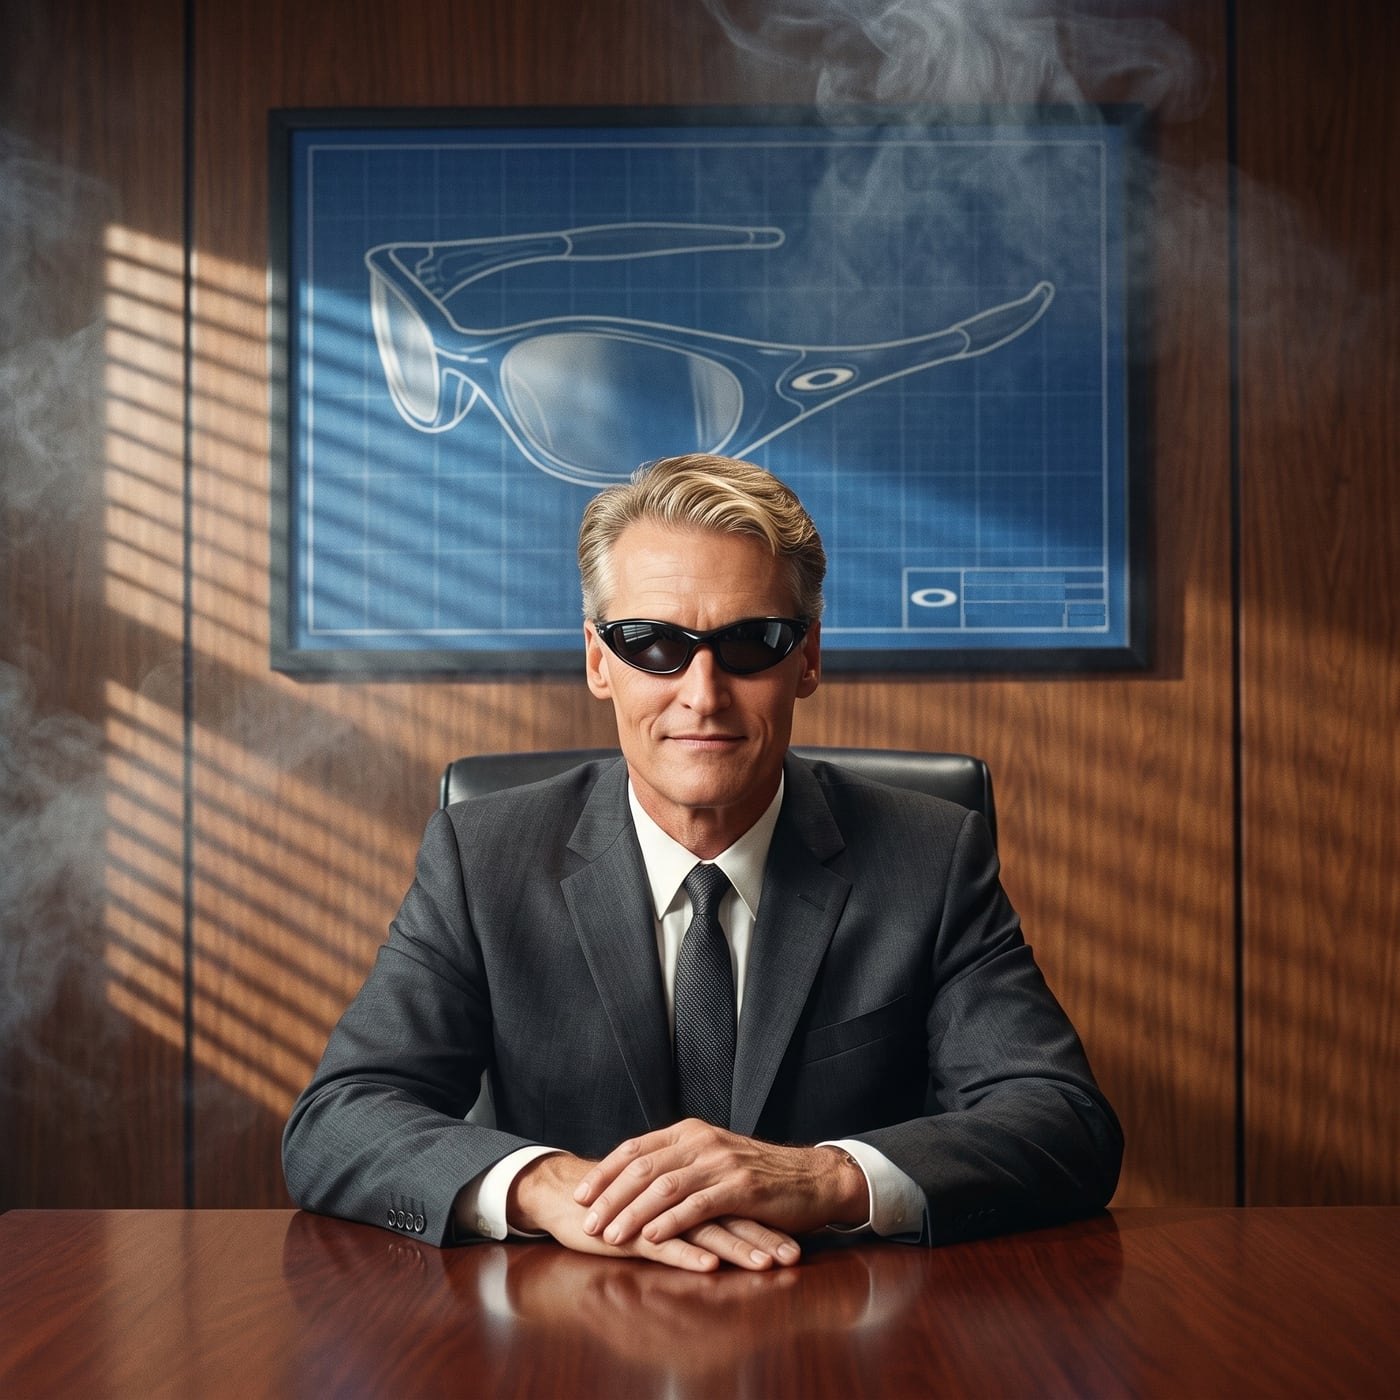
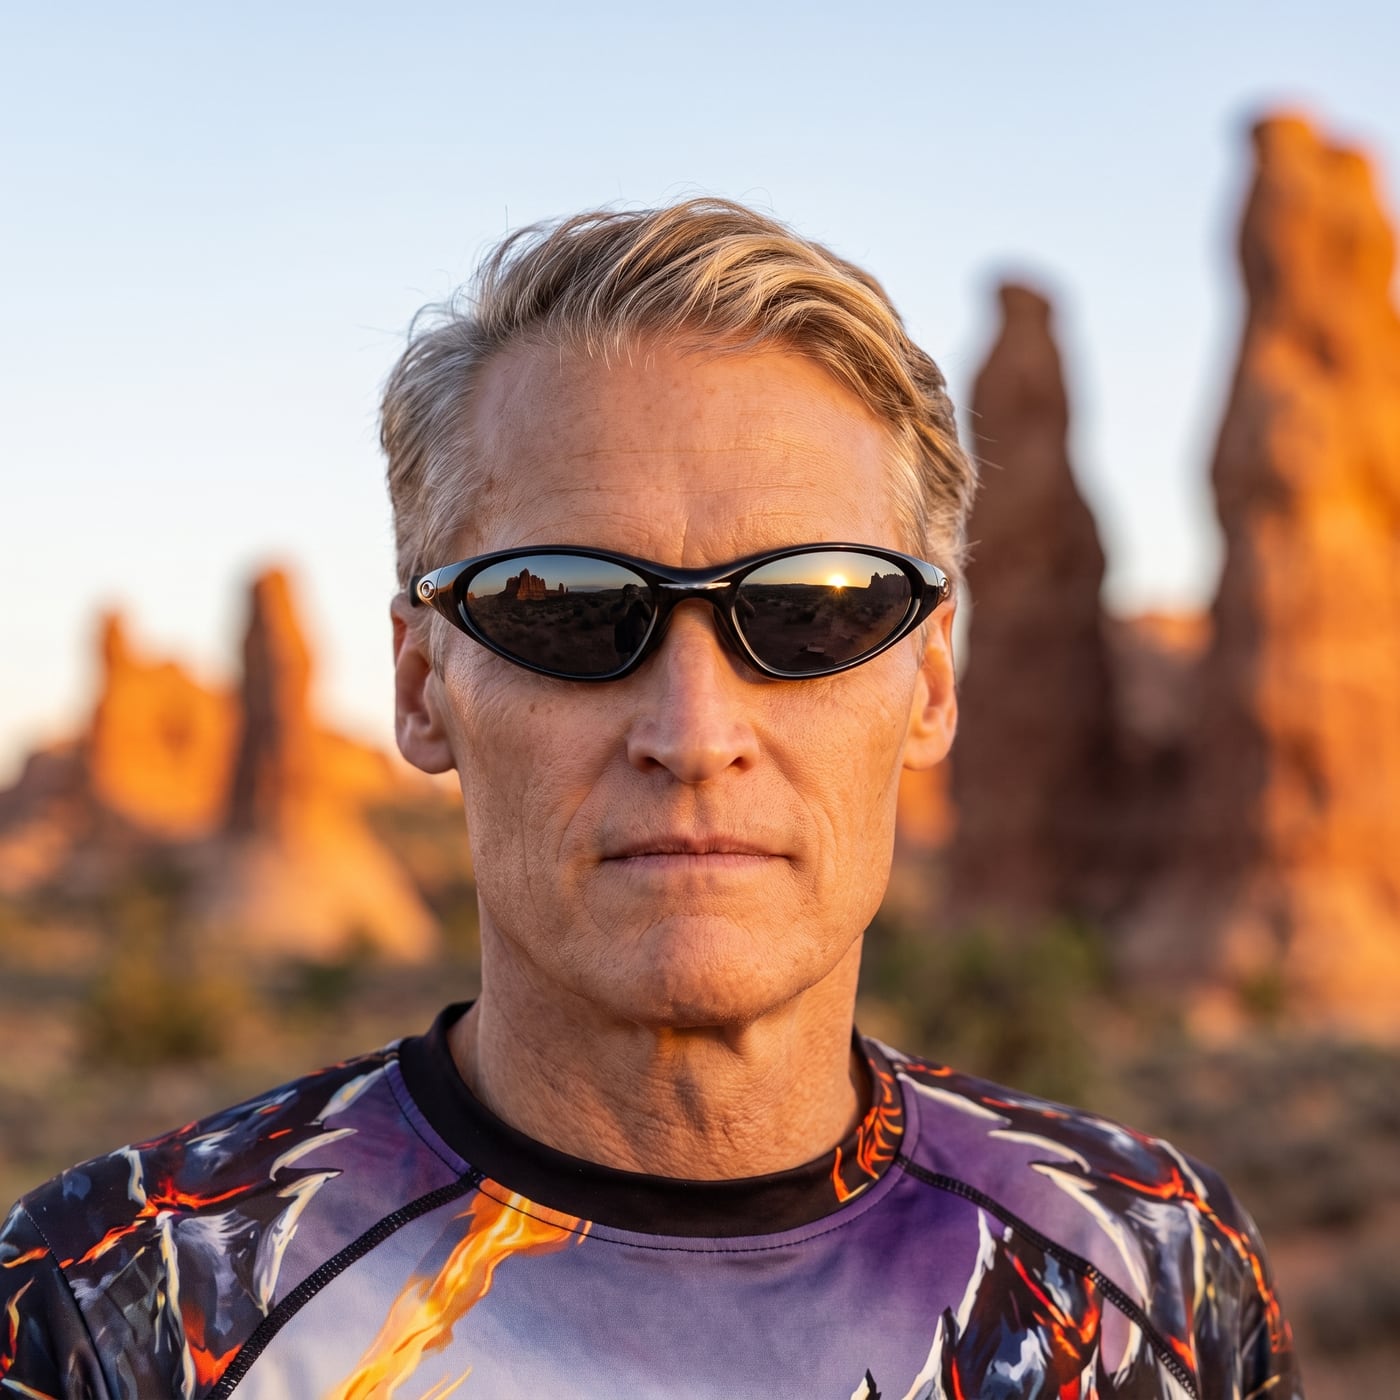
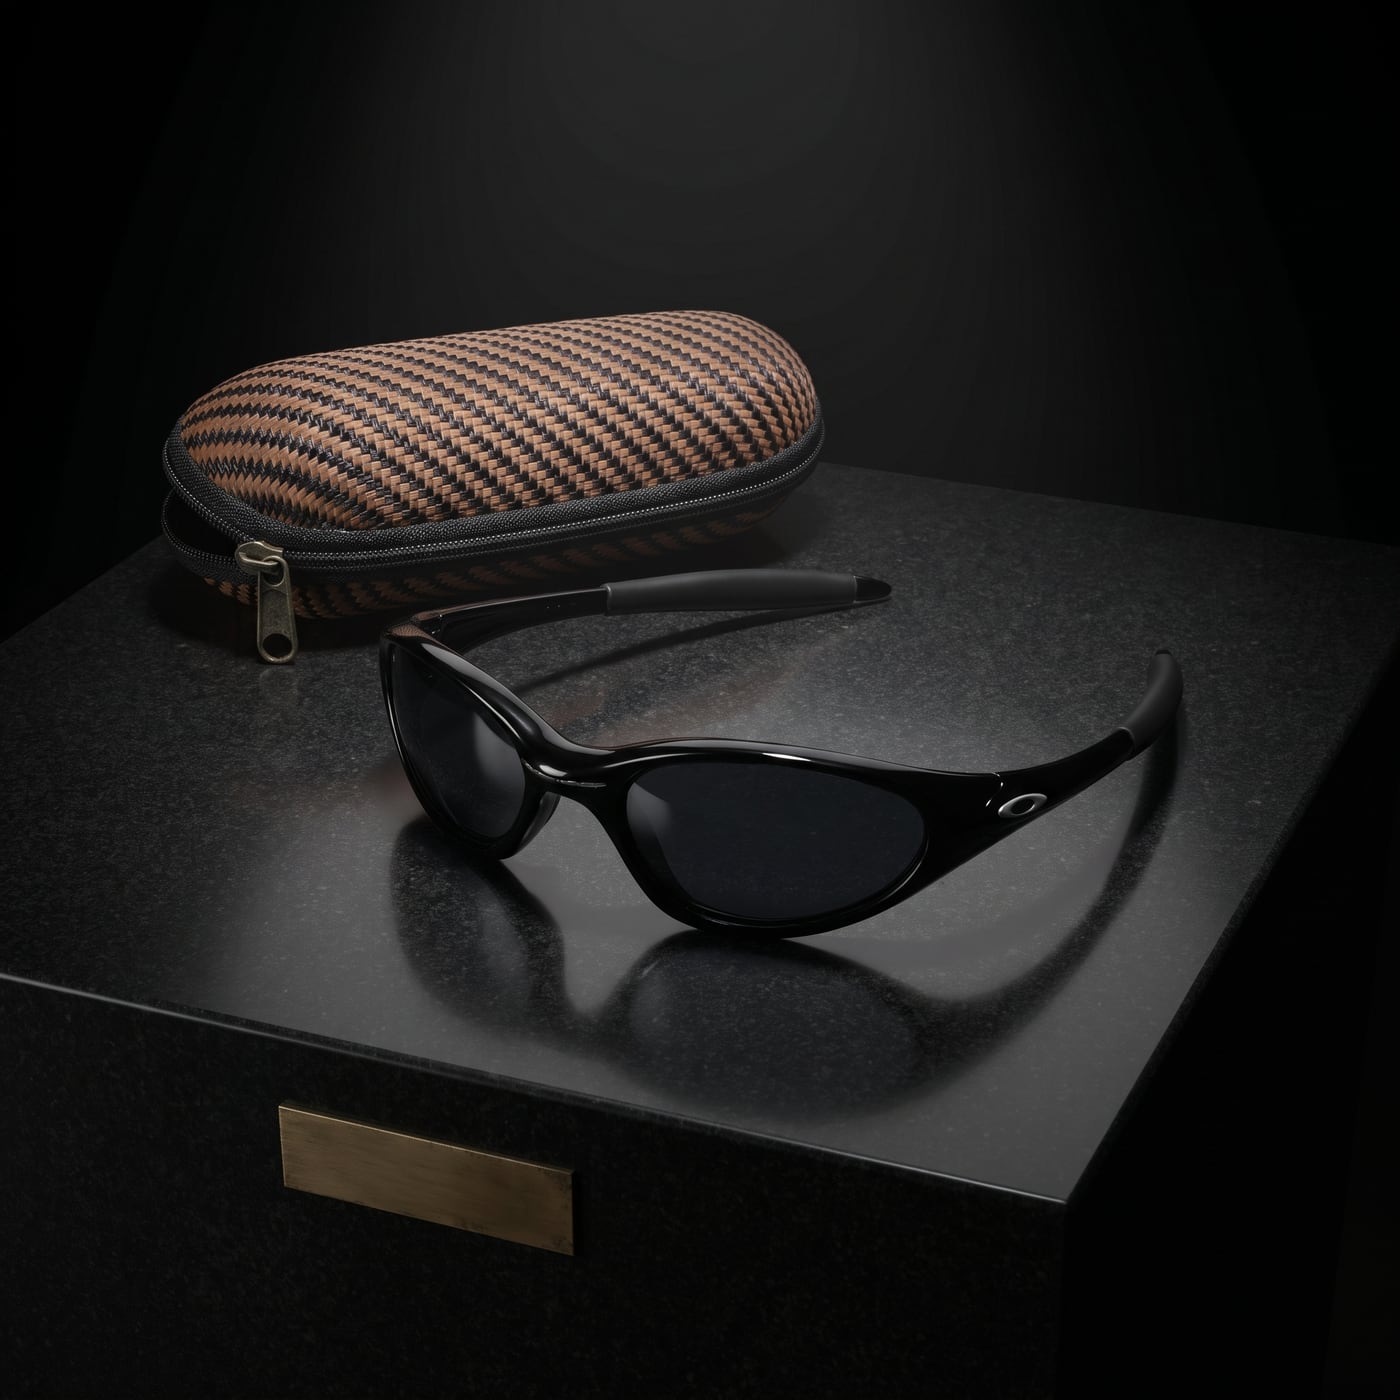
The product is CharacterCanvas.ai, an image-generation app I built end-to-end with Claude Code. The test was a five-scene ad campaign starring me and a pair of 1999 Oakley New Eye Jackets — a boardroom portrait, a windsurfing hero shot, a museum-grade product still, a Y2K chrome poster, and a black-and-white reveal. Same five prompts, same reference images, three contenders: my app, ChatGPT, and Gemini.
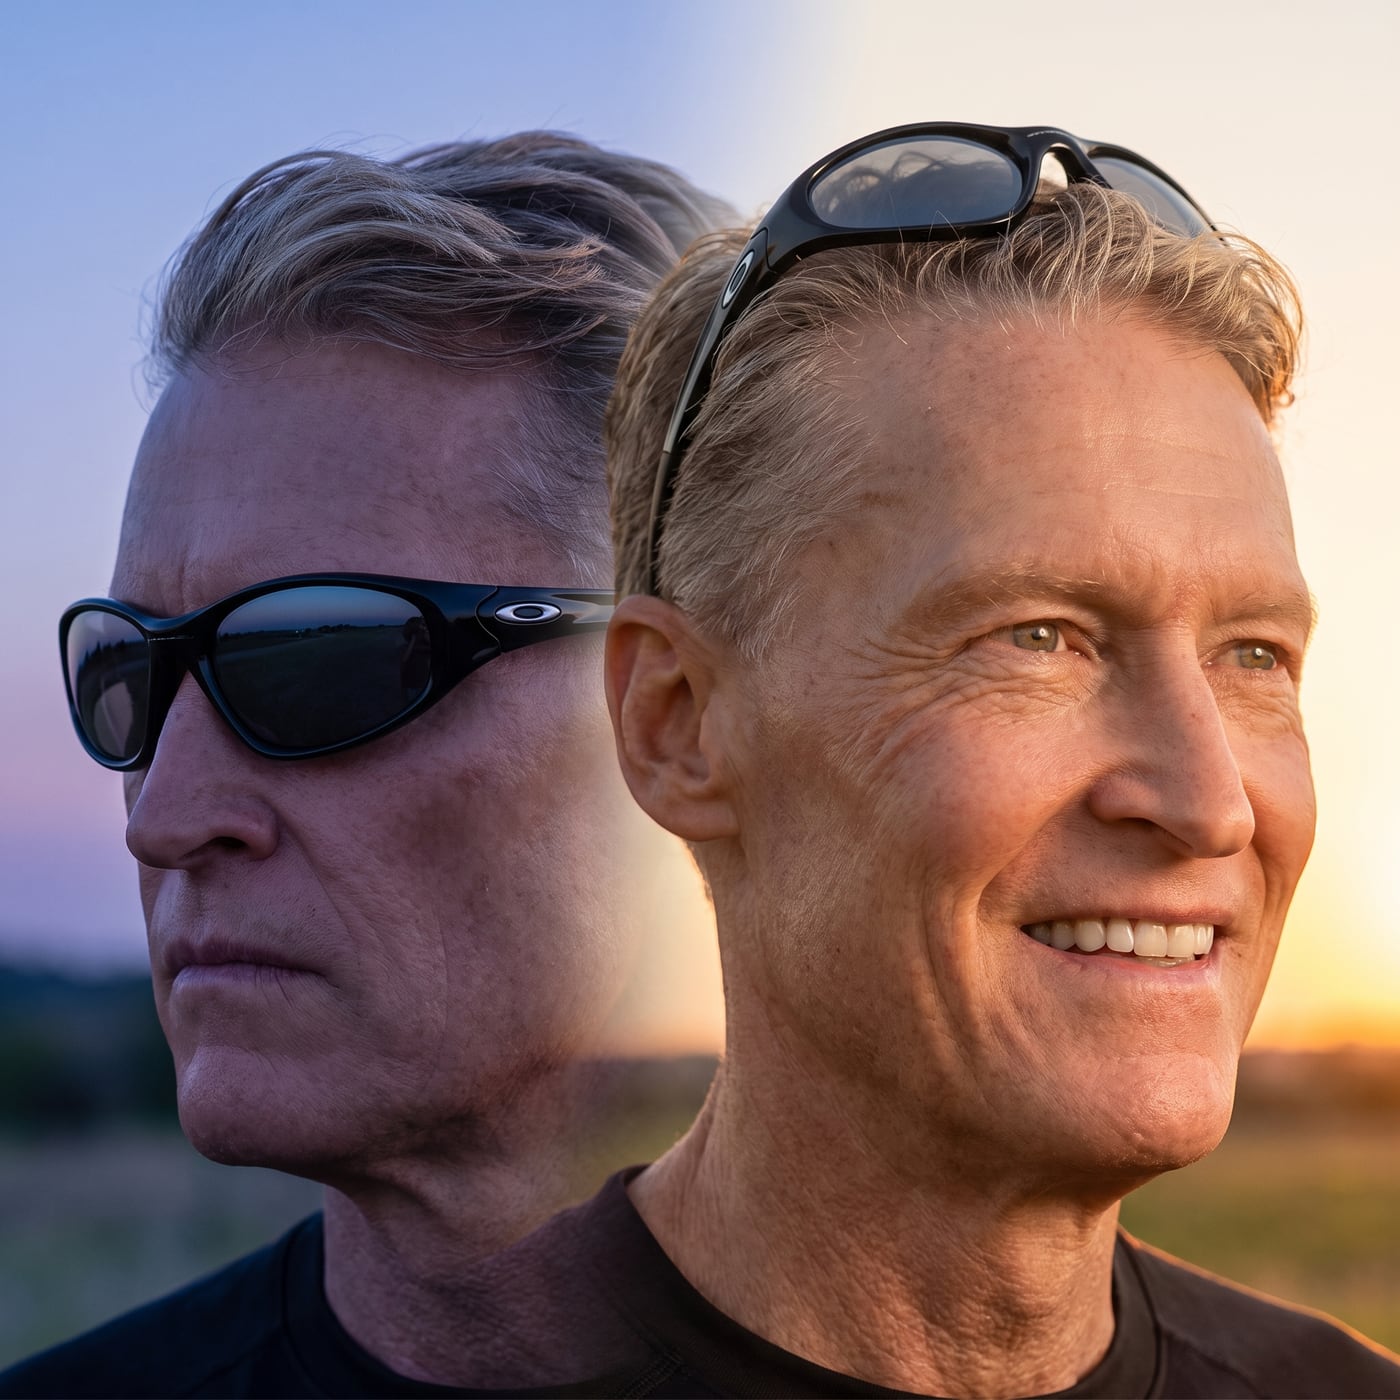
Somewhere in the middle of that experiment I ran into a truth every AI application builder eventually hits, and few say out loud.
Same model does not mean same result.
My app runs on Gemini’s image model — a backend I chose after dozens of comparative tests for reliability and speed. So the same prompt through my app and through the Gemini app should produce the same quality. It doesn’t. The consumer app wins on facial likeness, and it isn’t close on hard cases. The identical phenomenon holds for ChatGPT: prompts pasted into the ChatGPT app beat the same prompts through the same company’s API.
The reason is that a consumer AI app is not a thin window onto a model. It is a harness. By the time your request reaches the weights, the platform has rewritten and expanded your prompt, attached your reference images at full fidelity with conversational context, tuned a dozen generation settings you never see, and — sometimes — routed you to a newer model snapshot than the one the public API serves. The developer pays retail for yesterday’s endpoint while the platform runs tomorrow’s for free. That is the vanishing horizon: every rendering gap you close with engineering, the platform can reopen with a release. The playing field isn’t just tilted; the other team owns the stadium, the ball, and the clock.
If your product’s promise is “better pixels than the platform,” you are on a treadmill you cannot win, subsidizing your competitor with every API call.
Here is what my benchmark actually showed, though, and why I’m publishing it happily. Across the five scenes, my app won three categories outright — the product still, the chrome poster, the portrait reveal — and it was the only contender that delivered finished advertisements: headline set, dek placed, logo locked, in one pass. It did this while carrying the raw-rendering handicap I just described. The categories it won weren’t rendering categories. They were harness categories: character persistence across generations, disciplined reference handling, composition that understands it is making an ad and not a picture.
That is the entire strategic lesson, and it generalizes far beyond image generation.
Never compete on the model. Compound on it. The model is the tide; you don’t out-swim a tide, you build the boat. Platforms must serve a billion generic users, which means they structurally cannot verticalize into your customer’s actual job — campaign-grade character advertising, in my case. The layers they won’t build are exactly the layers you can own: workflow, persistence, brand context, output formats that match how the work is actually used, and the accumulated assets of your users’ own worlds.
Compounding also dictates architecture. If the platforms’ improvements are the tide, make your product a boat that rises with it: model-agnostic routing, so every upgrade any platform ships — including those unfair app-side snapshots when they eventually reach the API — becomes a free upgrade to you rather than a threat. The asymmetry flips. They spend billions improving engines; you capture the delta with a configuration change.
There is one more discipline this forces, and it is where most AI products quietly die: economics. The obvious way to close a quality gap is brute force — generate a dozen candidates, score them, show the best. It works in a demo and kills a product. Five times the cost, five times the wait, and a user who came for speed now watches a spinner while their price goes up. Nobody pays for that.
The answer is to move the search offline. The dozens-of-candidates comparison is genuinely valuable — as an engineering activity, run once, on a fixed benchmark, to discover the prompt templates, reference handling, and settings that make every future single shot better. Spend the compute at build time; ship the findings as defaults; keep runtime at one generation, one credit, a few seconds. Reserve extra compute for exactly two honest places: a strict quality gate that retries only genuine failures, and a clearly labeled premium tier for users who choose to pay for a second pass. Quality per credit per second is the metric. Everything else is vanity.
None of this makes the asymmetry fair. The platforms will keep their private snapshots and their zero marginal cost, and the horizon will keep receding for anyone chasing raw output quality. Let it. The builders who last on frontier platforms are the ones who stop competing with the engine and start compounding on top of it — who treat every model release as a rising tide under a boat the platform has no interest in building.
I benchmarked my own app expecting to lose. It took three of five categories and swept the one that matters most to my customers. Not because my renderer is better — it isn’t — but because the product was never the renderer.
The product is the harness. It always was.
Lindsay Hiebert is CMO & AI Officer at Nybsys and the builder of a portfolio of AI applications including CharacterCanvas.ai (cc-ai.co), developed end-to-end with Claude Code. The full benchmark images and prompts are in the companion post, “The Power to See.”
Get the next post
One honest note when we publish. No spam, ever.